

×
1 Choose EITC/EITCA Certificates
2 Learn and take online exams
3 Get your IT skills certified

Confirm your IT skills and competencies under the European IT Certification framework from anywhere in the world fully online.

EITCA Academy

Digital skills attestation standard by the European IT Certification Institute aiming to support Digital Society development

LOG IN TO YOUR ACCOUNT

CREATE AN ACCOUNT FORGOT YOUR PASSWORD?

FORGOT YOUR PASSWORD?

AAH, WAIT, I REMEMBER NOW!

CREATE AN ACCOUNT

ALREADY HAVE AN ACCOUNT?
EUROPEAN INFORMATION TECHNOLOGIES CERTIFICATION ACADEMY - ATTESTING YOUR PROFESSIONAL DIGITAL SKILLS
  • SIGN UP
  • LOGIN
  • INFO

EITCA Academy

EITCA Academy

The European Information Technologies Certification Institute - EITCI ASBL

Certification Provider

EITCI Institute ASBL

Brussels, European Union

Governing European IT Certification (EITC) framework in support of the IT professionalism and Digital Society

  • CERTIFICATES
    • EITCA ACADEMIES
      • EITCA ACADEMIES CATALOGUE<
      • EITCA/CG COMPUTER GRAPHICS
      • EITCA/IS INFORMATION SECURITY
      • EITCA/BI BUSINESS INFORMATION
      • EITCA/KC KEY COMPETENCIES
      • EITCA/EG E-GOVERNMENT
      • EITCA/WD WEB DEVELOPMENT
      • EITCA/AI ARTIFICIAL INTELLIGENCE
    • EITC CERTIFICATES
      • EITC CERTIFICATES CATALOGUE<
      • COMPUTER GRAPHICS CERTIFICATES
      • WEB DESIGN CERTIFICATES
      • 3D DESIGN CERTIFICATES
      • OFFICE IT CERTIFICATES
      • BITCOIN BLOCKCHAIN CERTIFICATE
      • WORDPRESS CERTIFICATE
      • CLOUD PLATFORM CERTIFICATENEW
    • EITC CERTIFICATES
      • INTERNET CERTIFICATES
      • CRYPTOGRAPHY CERTIFICATES
      • BUSINESS IT CERTIFICATES
      • TELEWORK CERTIFICATES
      • PROGRAMMING CERTIFICATES
      • DIGITAL PORTRAIT CERTIFICATE
      • WEB DEVELOPMENT CERTIFICATES
      • DEEP LEARNING CERTIFICATESNEW
    • CERTIFICATES FOR
      • EU PUBLIC ADMINISTRATION
      • TEACHERS AND EDUCATORS
      • IT SECURITY PROFESSIONALS
      • GRAPHICS DESIGNERS & ARTISTS
      • BUSINESSMEN AND MANAGERS
      • BLOCKCHAIN DEVELOPERS
      • WEB DEVELOPERS
      • CLOUD AI EXPERTSNEW
  • FEATURED
  • SUBSIDY
  • HOW IT WORKS
  •   IT ID
  • ABOUT
  • CONTACT
  • MY ORDER
    Your current order is empty.
EITCIINSTITUTE
CERTIFIED

Why is the concept of exploration versus exploitation important in reinforcement learning, and how is it typically balanced in practice?

by EITCA Academy / Tuesday, 11 June 2024 / Published in Artificial Intelligence, EITC/AI/ARL Advanced Reinforcement Learning, Prediction and control, Model-free prediction and control, Examination review

The concept of exploration versus exploitation is fundamental in the realm of reinforcement learning (RL), particularly within the scope of prediction and control in model-free environments. This duality is important because it addresses the core challenge of how an agent can effectively learn to make decisions that maximize cumulative rewards over time.

In reinforcement learning, an agent interacts with an environment through a series of actions, observations, and rewards. The agent's goal is to learn a policy—a mapping from states of the environment to actions—that maximizes the expected cumulative reward, often referred to as the return. To achieve this, the agent must balance two competing objectives: exploration and exploitation.

Exploration involves trying out new actions to discover their effects and the rewards they yield. This is essential for the agent to gather information about the environment, especially in the early stages of learning when it has limited knowledge. Without sufficient exploration, the agent might miss out on potentially rewarding actions and state-action pairs that could lead to higher returns.

Exploitation, on the other hand, involves choosing actions that the agent currently believes to yield the highest reward based on its existing knowledge. This is essential for the agent to capitalize on its learned policy and achieve high rewards. However, excessive exploitation can lead to suboptimal performance if the agent's knowledge is incomplete or inaccurate.

Balancing exploration and exploitation is critical because both are necessary for effective learning. Too much exploration can result in wasted effort on suboptimal actions, while too much exploitation can cause the agent to converge prematurely to a suboptimal policy. This balance is typically managed through various strategies and algorithms.

One common approach to balance exploration and exploitation is the ε-greedy strategy. In this method, the agent chooses a random action with probability ε (exploration) and the action that maximizes the expected reward with probability 1-ε (exploitation). The value of ε can be fixed or decay over time, allowing the agent to explore more in the early stages of learning and exploit more as it gains confidence in its policy.

Another approach is the use of Upper Confidence Bound (UCB) algorithms. UCB methods balance exploration and exploitation by considering not only the expected reward of an action but also the uncertainty or variance associated with that action. Actions with higher uncertainty are given a higher priority for exploration, ensuring that the agent does not overlook potentially rewarding actions.

In the context of model-free reinforcement learning, Temporal Difference (TD) learning methods, such as Q-learning and SARSA, are commonly used. These methods update the value function or Q-values based on the difference between the predicted and actual rewards. While these methods inherently involve some degree of exploration, they often incorporate ε-greedy or other exploration strategies to ensure a proper balance.

For example, in Q-learning, the agent updates its Q-values using the Bellman equation:
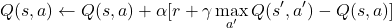
    \[ Q(s, a) \leftarrow Q(s, a) + \alpha [r + \gamma \max_{a'} Q(s', a') - Q(s, a)] \]

where \alpha is the learning rate, \gamma is the discount factor, r is the reward, s and s' are the current and next states, and a and a' are the current and next actions. The term \max_{a'} Q(s', a') represents the maximum expected future reward, encouraging exploitation. However, the agent typically uses an ε-greedy policy to select actions, ensuring exploration.
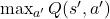
In SARSA (State-Action-Reward-State-Action), the update rule is slightly different:
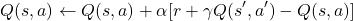
    \[ Q(s, a) \leftarrow Q(s, a) + \alpha [r + \gamma Q(s', a') - Q(s, a)] \]

Here, the next action a' is also chosen based on the agent's policy, which can incorporate exploration strategies like ε-greedy.

Another advanced method for balancing exploration and exploitation is the use of Bayesian approaches, where the agent maintains a probability distribution over the expected rewards for each action. This allows the agent to quantify uncertainty and make more informed decisions about when to explore and when to exploit.

Deep reinforcement learning methods, such as Deep Q-Networks (DQN), also employ exploration strategies. In DQN, a neural network is used to approximate the Q-values, and the agent typically uses an ε-greedy policy to balance exploration and exploitation. Additionally, techniques like experience replay and target networks help stabilize learning and improve the efficiency of exploration.

The Multi-Armed Bandit problem is a classic example that illustrates the exploration-exploitation dilemma. In this problem, an agent must choose between multiple slot machines (bandits), each with an unknown probability distribution of rewards. The agent must decide which bandit to play to maximize its cumulative reward. Various strategies, such as ε-greedy, UCB, and Thompson Sampling, are used to balance exploration and exploitation in this context.

In practice, the choice of exploration-exploitation strategy and its parameters depends on the specific problem and environment. Factors such as the complexity of the environment, the availability of prior knowledge, and the computational resources can influence the optimal balance. Researchers and practitioners often experiment with different strategies and tune parameters to achieve the best performance.

To illustrate, consider an agent learning to play a video game. In the early stages, the agent might use a high value of ε to explore different actions and understand the game's mechanics. As the agent gains experience and learns which actions lead to higher scores, it can gradually reduce ε, focusing more on exploiting its learned policy to achieve higher scores.

The exploration versus exploitation trade-off is a central challenge in reinforcement learning. Balancing these two objectives is essential for effective learning and achieving optimal performance. Various strategies and algorithms, such as ε-greedy, UCB, and Bayesian approaches, are used to manage this balance in practice. The choice of strategy and its parameters can significantly impact the agent's learning efficiency and overall performance.

Other recent questions and answers regarding Examination review:

  • How does Double Q-Learning mitigate the overestimation bias inherent in standard Q-Learning algorithms?
  • What is the key difference between on-policy learning (e.g., SARSA) and off-policy learning (e.g., Q-learning) in the context of reinforcement learning?
  • How does the Monte Carlo method estimate the value of a state or state-action pair in reinforcement learning?
  • What is the main advantage of model-free reinforcement learning methods compared to model-based methods?

More questions and answers:

  • Field: Artificial Intelligence
  • Programme: EITC/AI/ARL Advanced Reinforcement Learning (go to the certification programme)
  • Lesson: Prediction and control (go to related lesson)
  • Topic: Model-free prediction and control (go to related topic)
  • Examination review
Tagged under: Artificial Intelligence, Bayesian Approaches, Deep Q-Networks, Exploitation, Exploration, Multi-Armed Bandit, Q-learning, Reinforcement Learning, SARSA, Temporal Difference Learning, Upper Confidence Bound
Home » Artificial Intelligence » EITC/AI/ARL Advanced Reinforcement Learning » Prediction and control » Model-free prediction and control » Examination review » » Why is the concept of exploration versus exploitation important in reinforcement learning, and how is it typically balanced in practice?

Certification Center

USER MENU

  • My Account

CERTIFICATE CATEGORY

  • EITC Certification (117)
  • EITCA Certification (9)

What are you looking for?

  • Introduction
  • How it works?
  • EITCA Academies
  • EITCI DSJC Subsidy
  • Full EITC catalogue
  • Your order
  • Featured
  •   IT ID
  • EITCA reviews (Medium publ.)
  • About
  • Contact

EITCA Academy is a part of the European IT Certification framework

The European IT Certification framework has been established in 2008 as a Europe based and vendor independent standard in widely accessible online certification of digital skills and competencies in many areas of professional digital specializations. The EITC framework is governed by the European IT Certification Institute (EITCI), a non-profit certification authority supporting information society growth and bridging the digital skills gap in the EU.
Eligibility for EITCA Academy 90% EITCI DSJC Subsidy support
90% of EITCA Academy fees subsidized in enrolment

    EITCA Academy Secretary Office

    European IT Certification Institute ASBL
    Brussels, Belgium, European Union

    EITC / EITCA Certification Framework Operator
    Governing European IT Certification Standard
    Access contact form or call +32 25887351

    Follow EITCI on X
    Visit EITCA Academy on Facebook
    Engage with EITCA Academy on LinkedIn
    Check out EITCI and EITCA videos on YouTube

    Funded by the European Union

    Funded by the European Regional Development Fund (ERDF) and the European Social Fund (ESF) in series of projects since 2007, currently governed by the European IT Certification Institute (EITCI) since 2008

    Information Security Policy | DSRRM and GDPR Policy | Data Protection Policy | Record of Processing Activities | HSE Policy | Anti-Corruption Policy | Modern Slavery Policy
    Select LanguageAfrikaansArabicBelarusianBengaliBosnianBulgarianCatalanChinese (Simplified)Chinese (Traditional)CroatianCzechDanishDutchEnglishEstonianFilipinoFinnishFrenchGeorgianGermanGreekHebrewHindiHungarianIndonesianItalianJapaneseJavaneseKoreanKurdishLatvianLithuanianMalayMongolianMyanmar (Burmese)NepaliNorwegianPashtoPersianPolishPortuguesePunjabiRomanianRussianSerbianSlovakSlovenianSpanishSwedishTamilTeluguThaiTurkishUkrainianUrduVietnamese
    function doGLTTranslate(lang_pair) {if(lang_pair.value)lang_pair=lang_pair.value;if(lang_pair=='')return;var lang=lang_pair.split('|')[1];if(typeof _gaq!='undefined'){_gaq.push(['_trackEvent', 'GTranslate', lang, location.hostname+location.pathname+location.search]);}else {if(typeof ga!='undefined')ga('send', 'event', 'GTranslate', lang, location.hostname+location.pathname+location.search);}var plang=location.hostname.split('.')[0];if(plang.length !=2 && plang.toLowerCase() != 'zh-cn' && plang.toLowerCase() != 'zh-tw' && plang != 'hmn' && plang != 'haw' && plang != 'ceb')plang='en';location.href=location.protocol+'//'+(lang == 'en' ? '' : lang+'.')+location.hostname.replace('www.', '').replace(RegExp('^' + plang + '[.]'), '')+glt_request_uri;}

    Automatically translate to your language

    Terms and Conditions | Privacy Policy
    EITCA Academy
    • EITCA Academy on social media
    EITCA Academy


    © 2008-2026  European IT Certification Institute
    Brussels, Belgium, European Union

    TOP

    We care about your privacy

    EITCI uses cookies and similar technologies to keep this site secure, remember your choices, provide personalized experience, measure the traffic, serve more relevant content and certification programmes. You can accept all cookies or customize your preferences. Cookies are variables used to store website specific information on your device to facilitate processing of data for personalized website visit, such as login to your account, accessing the programmes, placing enrolment orders in chosen programmes and improving your EITC certification journey. You can change or withdraw your consent at any time by clicking the Consent Preferences button at the left-bottom of your screen. We respect your choices and are committed to providing you with a transparent and secure browsing experience, which may be limited when cookies aren't accepted. For more details refer to the Privacy Policy
    Customize Consent Preferences
    We use cookies to help you navigate efficiently and perform certain functions. You will find detailed information about all cookies under each consent category below.
    The cookies categorized as Necessary are stored on your browser as they are essential for enabling the basic functionalities of the site.
    To learn more about how Google processes personal information, visit: Google privacy policy

    Necessary

    Always Active

    Necessary cookies are required to enable the basic features of this site, such as providing secure log-in or adjusting your consent preferences. These cookies do not store any personally identifiable data.

    Functional

    Functional cookies help perform certain functionalities like sharing the content of the website on social media platforms, collecting feedback, and other third-party features.

    Preferences

    Stores personalization choices such as interface preferences.

    External media and social features

    Allows embedded video, social, chat, and external interactive services that may set their own cookies. Keep off until the user chooses these features.

    Analytics

    Performance cookies are used to understand and analyze the key performance indexes of the website which helps in delivering a better user experience for the visitors.

    Marketing and conversions

    Advertisement cookies are used to provide visitors with customized advertisements based on the pages you visited previously and to analyze the effectiveness of the ad campaigns.

    CHAT WITH SUPPORT
    Do you have any questions?
    Attach files with the paperclip or paste screenshots into the message box (Ctrl+V). Max 5 file(s), 10 MB each.
    We will reply here and by email. Your conversation is tracked with a support token.