Does the activation function run on the input or output data of a layer?
In the context of deep learning and neural networks, the activation function is a important component that operates on the output data of a layer. This process is integral to introducing non-linearity into the model, enabling it to learn complex patterns and relationships within the data. To elucidate this concept comprehensively, let us consider the mechanics of neural networks, the role of activation functions, and how they are applied to the output data of layers.
Neural Network Structure
A neural network consists of multiple layers, each comprising several neurons or nodes. These layers can be categorized into three types:
1. Input Layer: This is the first layer of the network, which receives the raw input data.
2. Hidden Layers: These layers are situated between the input and output layers. They perform various computations and transformations on the data.
3. Output Layer: This is the final layer of the network, which produces the output predictions.
Each neuron in a layer is connected to neurons in the subsequent layer through weighted connections. The weights and biases associated with these connections are learned during the training process to minimize the error in predictions.
Role of Activation Functions
Activation functions are mathematical functions applied to the output of each neuron in a layer before passing it to the next layer. The primary purposes of activation functions are:
1. Introduction of Non-Linearity: Without activation functions, neural networks would merely be linear models, regardless of the number of layers. Linear models are limited in their ability to capture complex patterns in data. Activation functions introduce non-linearity, enabling the network to learn and approximate more intricate functions.
2. Normalization: Activation functions can also help in normalizing the output of neurons, ensuring that the values remain within a specific range. This can prevent issues such as exploding or vanishing gradients during training.
Application of Activation Functions
Activation functions operate on the output data of a layer, which is the result of the weighted sum of inputs plus a bias term. Mathematically, this can be represented as follows for a single neuron:
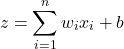
where:
–  is the pre-activation output.
–  are the weights.
–  are the input features.
–  is the bias term.
The activation function  is then applied to this pre-activation output to produce the final output of the neuron:

This activated output  is then passed as input to the neurons in the next layer.
Common Activation Functions
Several activation functions are commonly used in deep learning, each with its unique properties and applications. Some of the most prevalent ones include:
1. Sigmoid Function: The sigmoid function squashes the input values to a range between 0 and 1. It is defined as:
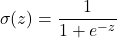
The sigmoid function is often used in binary classification problems. However, it can suffer from the vanishing gradient problem, where gradients become very small for large positive or negative input values, slowing down the training process.
2. Hyperbolic Tangent (Tanh) Function: The tanh function maps input values to a range between -1 and 1. It is defined as:
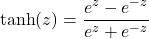
The tanh function is similar to the sigmoid function but has a broader output range, making it more suitable for hidden layers in some cases.
3. Rectified Linear Unit (ReLU): The ReLU function is defined as:
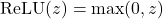
ReLU is widely used due to its simplicity and effectiveness. It helps mitigate the vanishing gradient problem and allows for faster training. However, ReLU can suffer from the "dying ReLU" problem, where neurons can become inactive if they output zero for all inputs.
4. Leaky ReLU: To address the dying ReLU problem, the Leaky ReLU introduces a small slope for negative input values. It is defined as:
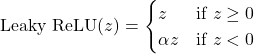
where  is a small positive constant.
5. Softmax Function: The softmax function is typically used in the output layer of a neural network for multi-class classification problems. It converts the raw output scores into probabilities that sum to 1. It is defined as:
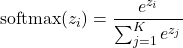
where  is the number of classes.
Implementation in PyTorch
In PyTorch, activation functions are readily available in the `torch.nn` module. Here is an example of how to implement a simple neural network with activation functions in PyTorch:
python
import torch
import torch.nn as nn
import torch.optim as optim

class SimpleNN(nn.Module):
    def __init__(self):
        super(SimpleNN, self).__init__()
        self.fc1 = nn.Linear(784, 128)  # Fully connected layer 1
        self.fc2 = nn.Linear(128, 64)   # Fully connected layer 2
        self.fc3 = nn.Linear(64, 10)    # Fully connected layer 3

        # Activation functions
        self.relu = nn.ReLU()
        self.softmax = nn.Softmax(dim=1)

    def forward(self, x):
        x = self.fc1(x)
        x = self.relu(x)  # Applying ReLU activation function
        x = self.fc2(x)
        x = self.relu(x)  # Applying ReLU activation function
        x = self.fc3(x)
        x = self.softmax(x)  # Applying Softmax activation function
        return x

# Example usage
model = SimpleNN()
criterion = nn.CrossEntropyLoss()
optimizer = optim.SGD(model.parameters(), lr=0.01)

# Dummy input data
input_data = torch.randn(64, 784)  # Batch size of 64, 784 features
target_labels = torch.randint(0, 10, (64,))  # Random target labels

# Forward pass
output = model(input_data)
loss = criterion(output, target_labels)

# Backward pass and optimization
loss.backward()
optimizer.step()
In this example, we define a simple neural network with three fully connected layers. We apply the ReLU activation function after the first and second layers to introduce non-linearity. Finally, we apply the softmax activation function in the output layer to obtain probability distributions for multi-class classification.Activation functions are essential in neural networks for introducing non-linearity and enabling the model to learn complex patterns. They are applied to the output data of a layer, transforming the pre-activation output into the activated output that is passed to the next layer. Various activation functions, such as sigmoid, tanh, ReLU, and softmax, serve different purposes and are chosen based on the specific requirements of the task at hand. PyTorch provides convenient implementations of these functions, facilitating the construction and training of neural networks.
Other recent questions and answers regarding Building neural network:
- What is the function used in PyTorch to send a neural network to a processing unit which would create a specified neural network on a specified device?
- In which cases neural networks can modify weights independently?
- Does Keras differ from PyTorch in the way that PyTorch implements a built-in method for flattening the data, while Keras does not, and hence Keras requires manual solutions like for example passing fake data through the model?
- How to measure the complexity of a neural network in terms of a number of variables and how large are some biggest neural networks models under such comparison?
- How does data flow through a neural network in PyTorch, and what is the purpose of the forward method?
- What is the purpose of the initialization method in the 'NNet' class?
- Why do we need to flatten images before passing them through the network?
- How do we define the fully connected layers of a neural network in PyTorch?
- What libraries do we need to import when building a neural network using Python and PyTorch?