What are accuracy, precision, recall, and F1 scores?
Accuracy, precision, recall, and F1 score are fundamental metrics used to evaluate the performance of classification models in machine learning. These metrics provide quantitative measures for assessing how well a model predicts the classes of input data, particularly in the context of supervised learning tasks such as binary classification, multiclass classification, and, in some adaptations, multilabel classification. Each metric captures a distinct aspect of model performance, and their interpretation is closely linked to the confusion matrix, a table that summarizes the performance of a classification algorithm by displaying the counts of true positives, true negatives, false positives, and false negatives.
1. Confusion Matrix: Foundation for Metrics
A confusion matrix is a 2×2 table (for binary classification) that enables the visualization of the performance of an algorithm. The matrix is typically organized as follows:
| Predicted Positive | Predicted Negative | |
|---|---|---|
| Actual Positive | True Positive (TP) | False Negative (FN) |
| Actual Negative | False Positive (FP) | True Negative (TN) |
– True Positive (TP): The number of instances that are correctly labeled as positive by the model.
– True Negative (TN): The number of instances that are correctly labeled as negative.
– False Positive (FP): The number of instances that are incorrectly labeled as positive (also called Type I error).
– False Negative (FN): The number of instances that are incorrectly labeled as negative (also called Type II error).
All of the discussed metrics derive their calculations from these four quantities.
2. Accuracy
Accuracy is the proportion of all predictions (both positive and negative) that the model correctly identifies. It is calculated as the ratio of correctly predicted observations (both TPs and TNs) to the total number of observations. Mathematically:
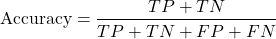
Accuracy provides an overall measure of correctness. For example, if a spam detection model classifies 950 emails correctly out of 1,000 total emails, the accuracy is 95%. However, accuracy may not be an informative metric when dealing with imbalanced datasets, where one class greatly outnumbers the other. In such cases, a model may achieve high accuracy by simply predicting the majority class all the time, thus misleadingly inflating performance.
3. Precision
Precision, also known as Positive Predictive Value, measures the proportion of positive predictions that are actually correct. It assesses the model's ability to avoid false positives. Precision is given by:
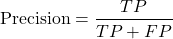
Precision is especially relevant when the cost of a false positive is high. For instance, in email spam detection, if the model predicts that an email is spam, precision indicates how many of the emails flagged as spam are indeed spam. High precision means that when the model flags something as positive, it is likely to be correct.
For example, consider a medical diagnostic test for a rare disease. If the model predicts 10 positive cases, out of which 8 are truly positive (TP) and 2 are false positives (FP), the precision is 8/10 = 0.8 or 80%.
4. Recall
Recall, also known as Sensitivity or True Positive Rate, measures the proportion of actual positive cases that are correctly identified by the model. Recall focuses on minimizing false negatives and is given by:
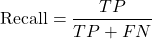
Recall is important in domains where missing a positive case is significantly more costly than a false alarm. For example, in cancer detection, failing to identify a positive case (i.e., a patient with cancer) could have severe consequences; thus, recall is prioritized.
Continuing the medical example, if there are 20 actual positive cases, but the model only correctly identifies 8 of them (TP), while missing 12 (FN), the recall is 8/20 = 0.4 or 40%.
5. The Trade-Off Between Precision and Recall
Precision and recall often have an inverse relationship; improving one can reduce the other. For example, by adjusting the threshold for positive classification, a model can be made more conservative (increasing precision but reducing recall) or more inclusive (increasing recall but reducing precision). This trade-off is context-dependent and should be managed based on the application’s requirements.
For instance, in financial fraud detection, high recall is important to catch as many fraudulent transactions as possible, even at the cost of some false positives (lower precision). Conversely, if the cost of investigating false alarms is very high, precision may be prioritized.
6. F1 Score
The F1 score provides a single metric that combines both precision and recall using their harmonic mean. It is especially useful when a balance between precision and recall is desired, or when the class distribution is uneven. The harmonic mean is preferred over the arithmetic mean because it punishes extreme values more; a high F1 score is only possible if both precision and recall are high.
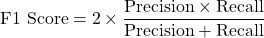
For the medical example above, with precision = 0.8 and recall = 0.4, the F1 score would be:
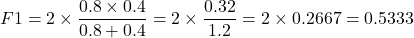
The F1 score ranges from 0 to 1, where 1 indicates perfect precision and recall.
7. Application to Imbalanced Datasets
In real-world applications, datasets are often imbalanced, meaning that one class (typically the negative or "normal" class) far outnumbers the other. For instance, in fraud detection, the number of fraudulent transactions is much smaller than the number of legitimate ones. In such cases, accuracy becomes a less informative metric, as a model could achieve high accuracy by simply always predicting the majority class.
Precision, recall, and F1 score provide more informative metrics in these scenarios:
– High Precision: Indicates few false positives. In fraud detection, this would mean few legitimate transactions are flagged as fraud.
– High Recall: Indicates few false negatives. In fraud detection, this would mean most fraudulent transactions are identified.
– F1 Score: Provides a balance, which is especially useful when neither false positives nor false negatives can be ignored.
8. Examples with Calculations
Consider a binary classification task with the following confusion matrix:
| Predicted Positive | Predicted Negative | |
|---|---|---|
| Actual Positive | 70 | 30 |
| Actual Negative | 10 | 90 |
From this, we have:
– TP = 70
– FN = 30
– FP = 10
– TN = 90
Calculations:
– Accuracy: (TP + TN) / (TP + TN + FP + FN) = (70 + 90) / (70 + 90 + 10 + 30) = 160 / 200 = 0.80 (80%)
– Precision: TP / (TP + FP) = 70 / (70 + 10) = 70 / 80 = 0.875 (87.5%)
– Recall: TP / (TP + FN) = 70 / (70 + 30) = 70 / 100 = 0.70 (70%)
– F1 Score: 2 x (Precision x Recall) / (Precision + Recall) = 2 x (0.875 x 0.70) / (0.875 + 0.70) = 2 x 0.6125 / 1.575 = 1.225 / 1.575 ≈ 0.778 (77.8%)
This example illustrates that while the accuracy is high, the model still misses 30 positive cases (false negatives), which could be significant depending on the application.
9. Multiclass and Multilabel Extensions
When dealing with more than two classes (multiclass classification), these metrics are typically computed per class and then averaged:
– Macro-average: Calculates the metric for each class independently and then takes the average, treating all classes equally.
– Micro-average: Aggregates the contributions of all classes to compute the average metric, giving more weight to classes with more samples.
– Weighted-average: Averages the metrics for each class, weighted by the number of true instances for each class.
For multilabel classification, where each instance can belong to multiple classes simultaneously, the same metrics are computed for each label and then averaged according to the same schemes.
10. Practical Considerations and Metric Selection
The choice of evaluation metric depends on the specific context and risks of the application. In medical diagnosis, recall is often prioritized to minimize the risk of missing positive cases. For spam filtering, precision may be more important to ensure legitimate emails are not incorrectly classified as spam. The F1 score is particularly useful when one needs a balanced measure that takes both types of errors into account, especially in imbalanced datasets.
11. Integration in Google Cloud Machine Learning
In the context of Google Cloud Machine Learning and similar platforms, these metrics are computed and visualized as part of model evaluation workflows. The platform often provides built-in functions to calculate these values on validation and test datasets, allowing practitioners to compare models and select the best-performing one based on the metrics most relevant to their business or research goals.
12. Summary Paragraph
Understanding accuracy, precision, recall, and F1 score is fundamental for evaluating classification models. Each metric provides distinct information: accuracy gives an overall fraction of correct predictions; precision quantifies the correctness of positive predictions; recall measures the ability to find all positive instances; and the F1 score balances the trade-off between precision and recall. The choice of metric should align with the real-world costs associated with different types of errors, and their interpretation should always consider the underlying class distribution and the specific requirements of the application.
Other recent questions and answers regarding What is machine learning:
- What is the difference between machine learning and artificial intelligence?
- Is AI a subset of machine learning and not vice versa?
- How to create a program to predict possible failures in a car? What programming language and libraries to use? And what algorithm to use?
- How can machine learning help in supply chain prediction and risk management?
- What are prominent and prospective specializations in AI?
- How can machine learning help me as an experienced translator and conference interpreter?
- How can I use machine learning in manufacturing?
- Finance or, better, trading (stocks, crypto, ETFs,…) requires a lot of data to be analyzed. How can I create a ML model to take into consideration all those factors—financial and non-financial, like human psychology, political events, weather?
- Would it be possible to use data with multiple language datasets included, where the algorithm has to use data from sources that are in different languages?
- Given that I want to train a model to recognize plastic types correctly, 1. What should be the correct model? 2. How should the data be labeled? 3. How do I ensure the data collected represents a real-world scenario of dirty samples?
View more questions and answers in What is machine learning